A QA lead at a fintech app told us her agent had 'passed' the checkout test for three weeks. It never reached the payment page. The prompt said, 'test the checkout,' so the agent decided the basket counted. A broken payment step had already shipped. Once the prompt named a goal, a starting state, and a confirmation message, the same flow began failing correctly.
Prompting QA is writing test instructions an AI agent can run without guessing. State the goal and starting state, list observable actions, and define the expected result as acceptance criteria. In agentic QA, this kind of flow leaves the agent less room to improvise. Below, we show how to write each part and keep results repeatable.
What Agentic QA Means for Testing Teams
What is an AI agent? It is software that works towards a goal by choosing its own actions with tools such as a browser. That is the definition of AI agent behaviour and the AI agent definition we use in QA. Agentic QA applies it to a whole user flow, and that is how we define agentic AI for testing.
- The agent controls: Navigation, element choice, and retries.
- Your team controls, through the prompt: The goal, starting state, data, and pass criteria.
Agentic AI examples in product testing include an agent that completes a checkout and reports what it saw. AI in software testing is moving from generating tests to executing them, and AI prompt engineering keeps that repeatable across AI-driven testing solutions. See our guide to AI testing tools.
How an AI Agent Differs from a Scripted Test Runner
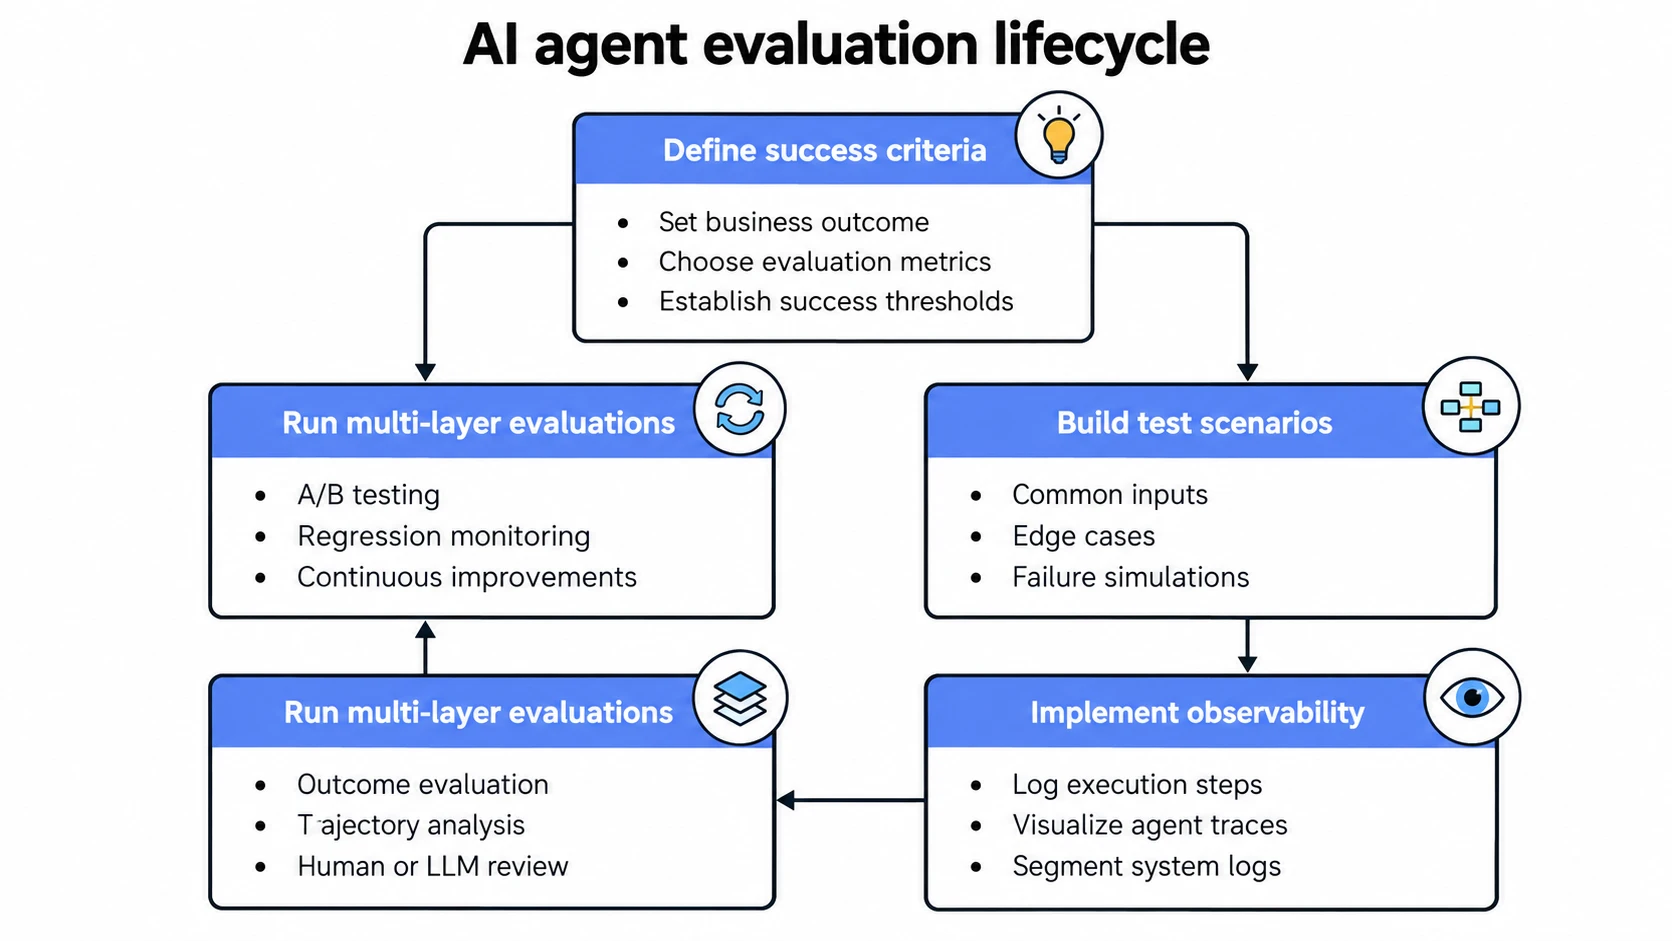
A scripted runner executes fixed steps against fixed selectors, so a renamed button breaks the run. An AI agent takes a goal and finds the path itself, much like a person doing manual testing, so small UI changes rarely stop it. The trade-off is that an agent can adapt wrongly, which is why your prompt must carry the pass criteria. Use the table to decide which flows to hand over.
Why Vague Prompts Make Agentic QA Unreliable
In AI testing, a vague prompt makes an agent fill every gap with an assumption, and each assumption lets two runs diverge. 'Test the checkout' might pay by card in one run and stop at the basket in the next.
Where Agents Guess and Test Results Drift
Agents guess wherever the prompt is silent, and four gaps cause most of the drift. Each one can be closed in the prompt.
- Starting state: Which account, basket, and environment the run begins in, such as a returning customer with an empty basket.
- Element choice: Which button counts when a page shows two.
- Data: What to type into each field, including edge values.
- Success: What 'done' looks like on screen.
Across our QA engagements, the most common cause of drifting agent verdicts is an unstated starting state, not the model. Fix that first, and flaky tests drop sharply. Retries only hide the problem.
How to Describe a User Flow So an Agent Can Test It
Write each of your user flows in three parts: The goal with its starting state, the steps as observable actions, and the expected results as acceptance criteria. Describe intent and visible behaviour, never locators that break when a button is renamed. Template the structure once, and it slots into your QA workflows, with each flow added to your test plan. The three sections below take each part in turn.
Start with the Goal and the Starting State
State the role, entry point, and account state before step one, in plain language. Anything you leave out, the agent invents.
- 'Returning customer on the Basic subscription plan.'
- 'Sign-up date 30 days ago.'
- 'Empty basket, staging.'
A dozen words like these stop the agent inventing a user, and they make any failure easy to reproduce. Keep one starting state per flow.
Write Steps as Observable Actions
Each step should be something a user does and a screen shows, one action per line. Describe the action, not the element, so a renamed button does not break the flow.
- Weak: 'Go to billing and upgrade.'
- Strong: 'Click Upgrade; the plan page shows Pro at £20 a month.'
Split long flows into shorter prompts. A twelve-step prompt gives the agent twelve chances to wander, and the failure is harder to locate.
Define Expected Results with Acceptance Criteria
The expected result is where agents drift most, because 'it works' cannot be checked. State exactly what the agent must see or find at the end of the flow.
Given a returning customer on the Basic subscription plan
When they upgrade to Pro with test card 4242
Then the page shows "Upgrade confirmed"
And the account plan is "Pro"
Plain sentences work too. Take any of your user story examples with acceptance criteria and rewrite them as end-to-end testing prompts. Then add negative test cases with boundary value test data:
- An expired card.
- A quantity of 0 or 10,001.
- A SQL command typed into a text field.
- An internet connection dropped mid-payment.
Prompting QA Examples: Weak vs. Strong User Flow Descriptions
Prompting QA examples are easiest to judge side by side. The strong prompts below double as acceptance criteria examples you can copy.
Checkout Flow Example
Weak prompt:
Test that the checkout works.Strong prompt:
Goal: a returning customer upgrades to Pro through checkout.
Start: logged in, Basic subscription plan, sign-up date 30 days ago, staging, seeded account A.
Steps: open Billing; click Upgrade; pay with test card 4242.
Pass: page shows "Upgrade confirmed"; plan is "Pro".
Fail case: card 4000 0000 0000 0002 shows "Card declined" with a support center link; plan stays "Basic".
The weak prompt lets the agent decide what 'works' means. The strong one states the start, the steps, and two outcomes, including the declined card most teams forget.
Login and Session Flow Example
Verification codes are the usual trap. The agent must know where to read the code, or it will improvise.
Goal: a registered user logs in and stays signed in for 30 minutes.
Start: account seeded through the CRM system API, 2FA enabled, fresh session.
Steps: open /login; enter email and password; read the code from the test inbox; submit.
Pass: dashboard shows the user's name; session token expires after 30 minutes.
Fail case: a wrong code three times locks the account and shows "Too many attempts".
Keep code retrieval, account creation, and token expiry deterministic. Let the agent drive the journey around them.
Making Agent-Run End-to-End Tests Repeatable
A good prompt is necessary but not sufficient. Agent verdicts only repeat when the test environment, the data, and the model stay fixed, so lock those down before you add more flows.
Control Test Data and Environments
Most drift comes from the world around the prompt. These controls remove the usual suspects:
- Test data setup: Seeded accounts, resettable data, and a pinned model version.
- Data Privacy: Use synthetic data, never real customer records. The same goes for research participants in usability studies.
- Stable test environment: Shared data and date-driven content, such as a sign-up date that triggers trial expiry, cause flaky tests.
- Security tooling: A security solution built to stop online attacks may block your agent, so ask the site owner to allow-list its IP addresses.
- Transport: Run over HTTP with SSL encryption, or certificate warnings pollute verdicts.
Retries are not a fix for drift. They only hide the assumption behind a flaky verdict.
Add Agent Tests to Your Regression Suite in CI/CD
Decide which flows stay scripted and which go to the agent. Keep stable flows in your test automation framework and test automation tools, use codeless test automation tools for simple recorded checks, and use AI test automation where scripts are costly to maintain. Let your test strategy give each layer one job. Whichever agentic AI tools you choose, from free AI agents to an open-source AI agent framework, agentic AI workflows slot into the same CI/CD pipeline as scripted checks:
- Run agent flows on deploys.
- Capture pass/fail evidence.
- Re-run a benchmark set whenever the prompt or model changes.
agent-e2e:
  on: deploy
  steps: [seed-test-data, run-agent-flows, upload-evidence]
End-to-end agent runs are system testing through the user's eyes, so schedule them where your system testing already runs. Keep performance & security checks in dedicated tools, and treat self-healing tests as suggestions until a person reviews them.
How Frugal Testing Helps You Test AI Agents
Whether you are building AI agents, buying custom AI agents, or using AI agent development services, we test how they behave before your customers see them. Our AI-assisted test automation service and software test automation services run each agent through real user flows and record every step it took and why.
Our software QA services then check outcomes, retries, and data use, and a security service review covers logins and payments. If you are working out how to create an AI agent, how to make an AI agent, or how to build your own AI agent, we write the test spec first.
What Our Agentic QA Engagement Looks Like
Each engagement has four checks, and each ends in something you keep.
- Flow coverage: We turn your critical journeys into agent-ready prompts. We provide a prompt library.
- Behaviour checks: We verify steps, retries, and data use across repeated runs. We provide a benchmark set.
- Risk review: We probe wrong actions, prompt injection, and data leaks. We provide a findings report.
- CI evidence: We run agent tests on every deploy. We provide a pipeline you own.
Conclusion
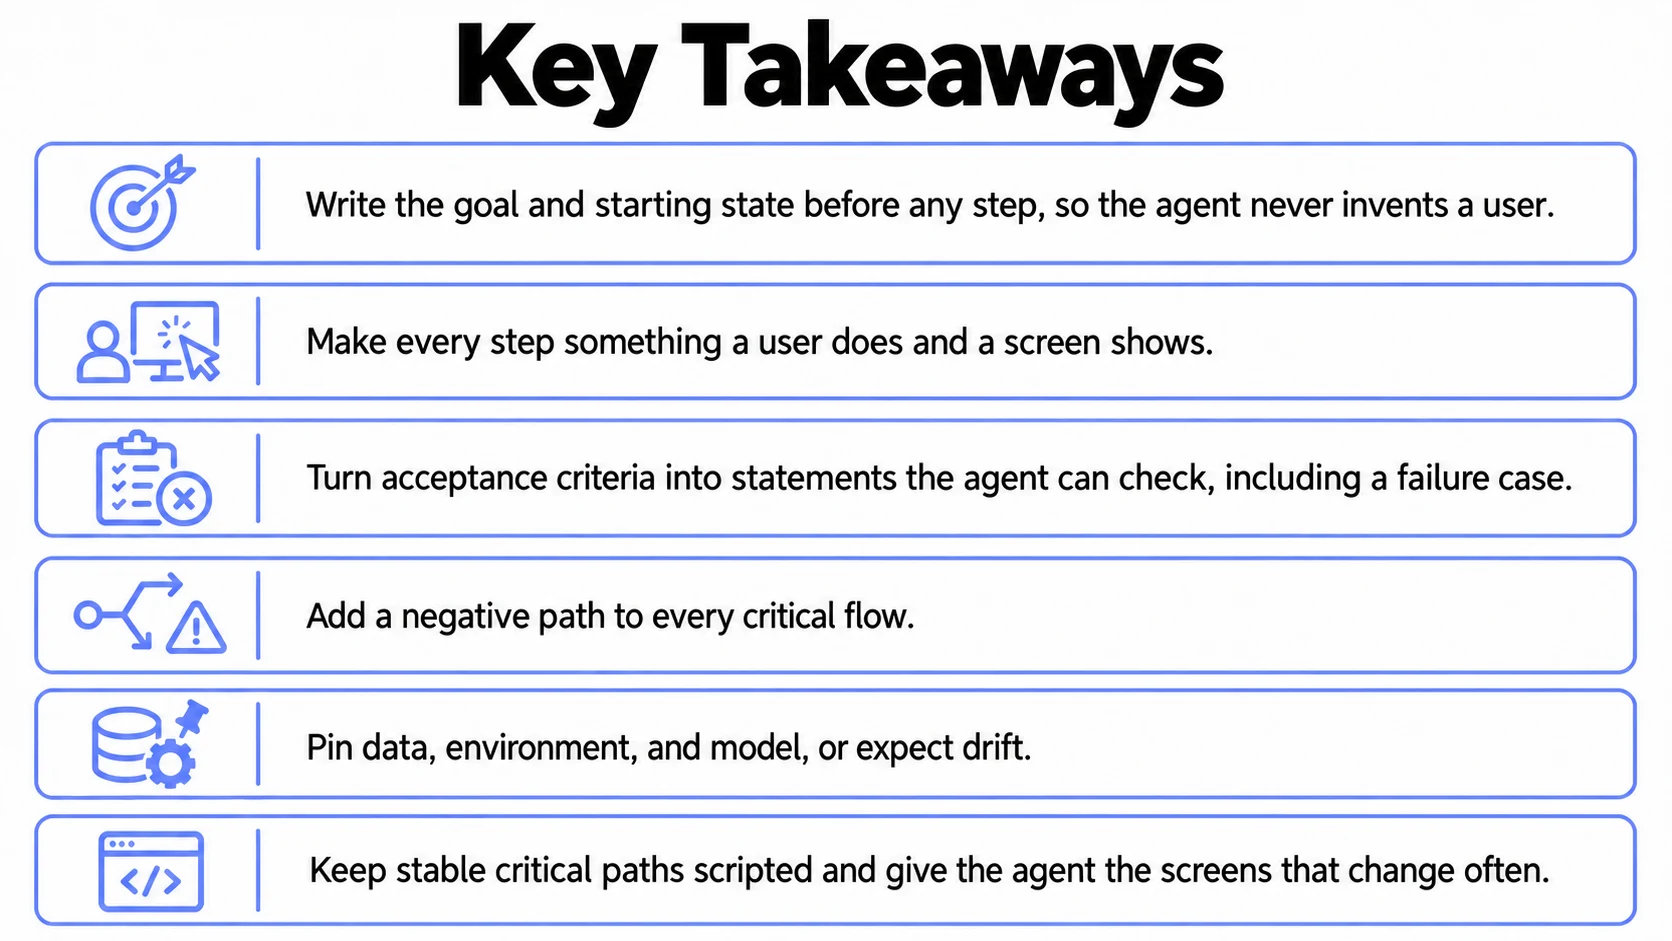
Prompting QA is not clever wording. It is the discipline of leaving nothing to chance: A clear goal, a known starting state, observable steps, and acceptance criteria the agent can check. Agentic QA rewards teams that write prompts like test specifications.
It punishes teams that treat prompts like chat messages. Start with your single most important flow, rewrite it in the three-part structure, and run it ten times. If the verdict changes even once, you have found the next blank to fill. That is the whole discipline.
Frequently Asked Questions
Q1. What Is an AI Agent and How Does It Work in QA Testing?
Ans: It works through a browser or API tool, guided by your prompt. Reliability comes from clear acceptance criteria and controlled test data, not from model size or clever wording.
Q2. What Is Test Automation in Software and Where Do AI Agents Fit?
Ans: Test automation in software means code runs your checks instead of a person clicking through them. Agents suit screens that change often, while stable payment paths usually stay scripted.
Q3. What Is Acceptance Criteria for an AI Agent Test?
Ans: Acceptance criteria are the conditions that decide whether a flow passes. For an agent, phrase each as visible text, a system state, or a stored record.
Q4. What Is AI Agent Testing and How Is It Different from Model Evaluation?
Ans: Model evaluation scores answers on a benchmark. AI agent testing checks full behaviour: Tool calls, retries, data use, and final outcomes across repeated runs on the same flow.
Q5. What Is the Best AI Agent Platform for QA Testing?
Ans: Judge any agentic AI platform on run logs and data controls. The best agentic AI and best AI agents are auditable, and the best AI agent builder shows every run.